Rebuilding the Traversal Agent Runtime on Temporal
Traversal is an AI SRE platform, built to keep the world’s most complex production environments running reliably. At the heart of Traversal is investigation: understanding why something broke. Agents reason over our Production World Model™, a live representation of how a customer's systems actually fit together, and our Causal Search Engine™ then narrows that enormous space of candidate signals—across multiple hops—down to the ones that explain the failure. It analyzes metrics, events, logs, traces, code, and deploys, opens a scoped shell against the customer's cluster when it needs a closer look, and delegates narrower lines of inquiry to sub-agents that report back into its reasoning.
That work is demanding. A single investigation makes dozens of model calls and runs many rounds of analysis. It runs while someone is watching a broken production system, so speed matters: every second spent finding the cause is a second the outage goes on. And it executes against a customer’s live environment, where partial failure is routine rather than exceptional: an API hangs, a model provider returns a 500, a pod gets rescheduled mid-run. The runtime underneath has to absorb all of that without losing work.
Two steps, two payoffs
When we first built our investigation agent, the focus was accuracy, and investigations ran directly inside our API server. As we grew from a research effort into a platform serving customers under our own SLAs, migrating to Temporal became a clear area for investment.
We planned the migration in two steps. The first moved execution onto Temporal workers, which gave us orchestration right away: scheduling, isolation, and automatic retry, without touching the agent. The second rebuilt the agent harness itself around Temporal primitives, where the full benefit of durable execution lives.
Step one: running on Temporal workers
The first migration put each investigation into a Temporal workflow that called a single activity.
An activity is Temporal's unit of work for anything that touches the outside world: calling a model, querying a customer's telemetry, writing to a database. Each activity carries its own timeouts and its own retry policy. Ours carried the entire investigation. The agent loop started inside the activity, ran until it reached a root cause, and returned a report.
Moving it in one piece was the appropriate sequencing to unblock early scaling. The orchestration benefits were available immediately, whereas rewriting the runtime and the agent at the same time, in the code path the entire product depends on, wasn't a trade worth making. This step delivered what we wanted from it: investigations came off the API's critical path and onto infrastructure built to schedule and supervise them.
What the first step left on the table
We knew a second step was coming. Durable execution applies at the boundaries you give it, and we had given it exactly one. Temporal could supervise an investigation but had no visibility into the steps inside it. That left three capabilities out of reach, and they made the case for step two concrete.
- Granular retry. When an investigation failed late in its budget, Temporal retried the activity from the top, exactly as configured. Every model call and every round of analysis that had already succeeded ran a second time.
- Resumption. Everything an investigation held, including the message history, the analysis in flight, and any background work, lived in a single process. When that process ended, so did all of it. Temporal could start another attempt, but a new attempt meant a new process, and the only place it could begin was the start of the pipeline.
- Elastic concurrency. A Temporal worker slot stayed occupied for the full duration of an investigation, so capacity scaled with the number of workers we ran. Alert-triggered investigations started competing with people opening sessions by hand. Separate worker pools bought us some headroom, but the underlying unit was still one investigation per slot.
Step two: rebuilding the harness with Temporal in mind
Two pressures pushed us into the second migration at once. One was infrastructure: the reliability and scalability gaps above. The other was the product experience. Humans and other agents should be able to steer and stop an investigation while it is running, and to do it the same way from every caller.
We considered adopting an existing agent harness instead of rebuilding our own. But ours is unusual: the research team updates it continuously to support new experiments, and a general-purpose harness would put a ceiling on that work. Owning the harness was needed; the open question was what to build it on.
Our answer was to rewrite the harness so the agent runs on Temporal’s primitives directly, instead of Temporal just supervising it from the outside. Durability, retry, cancellation, and scheduling stopped being behaviors we maintained around the agent and became properties of how the agent executes. Four changes carried the migration.
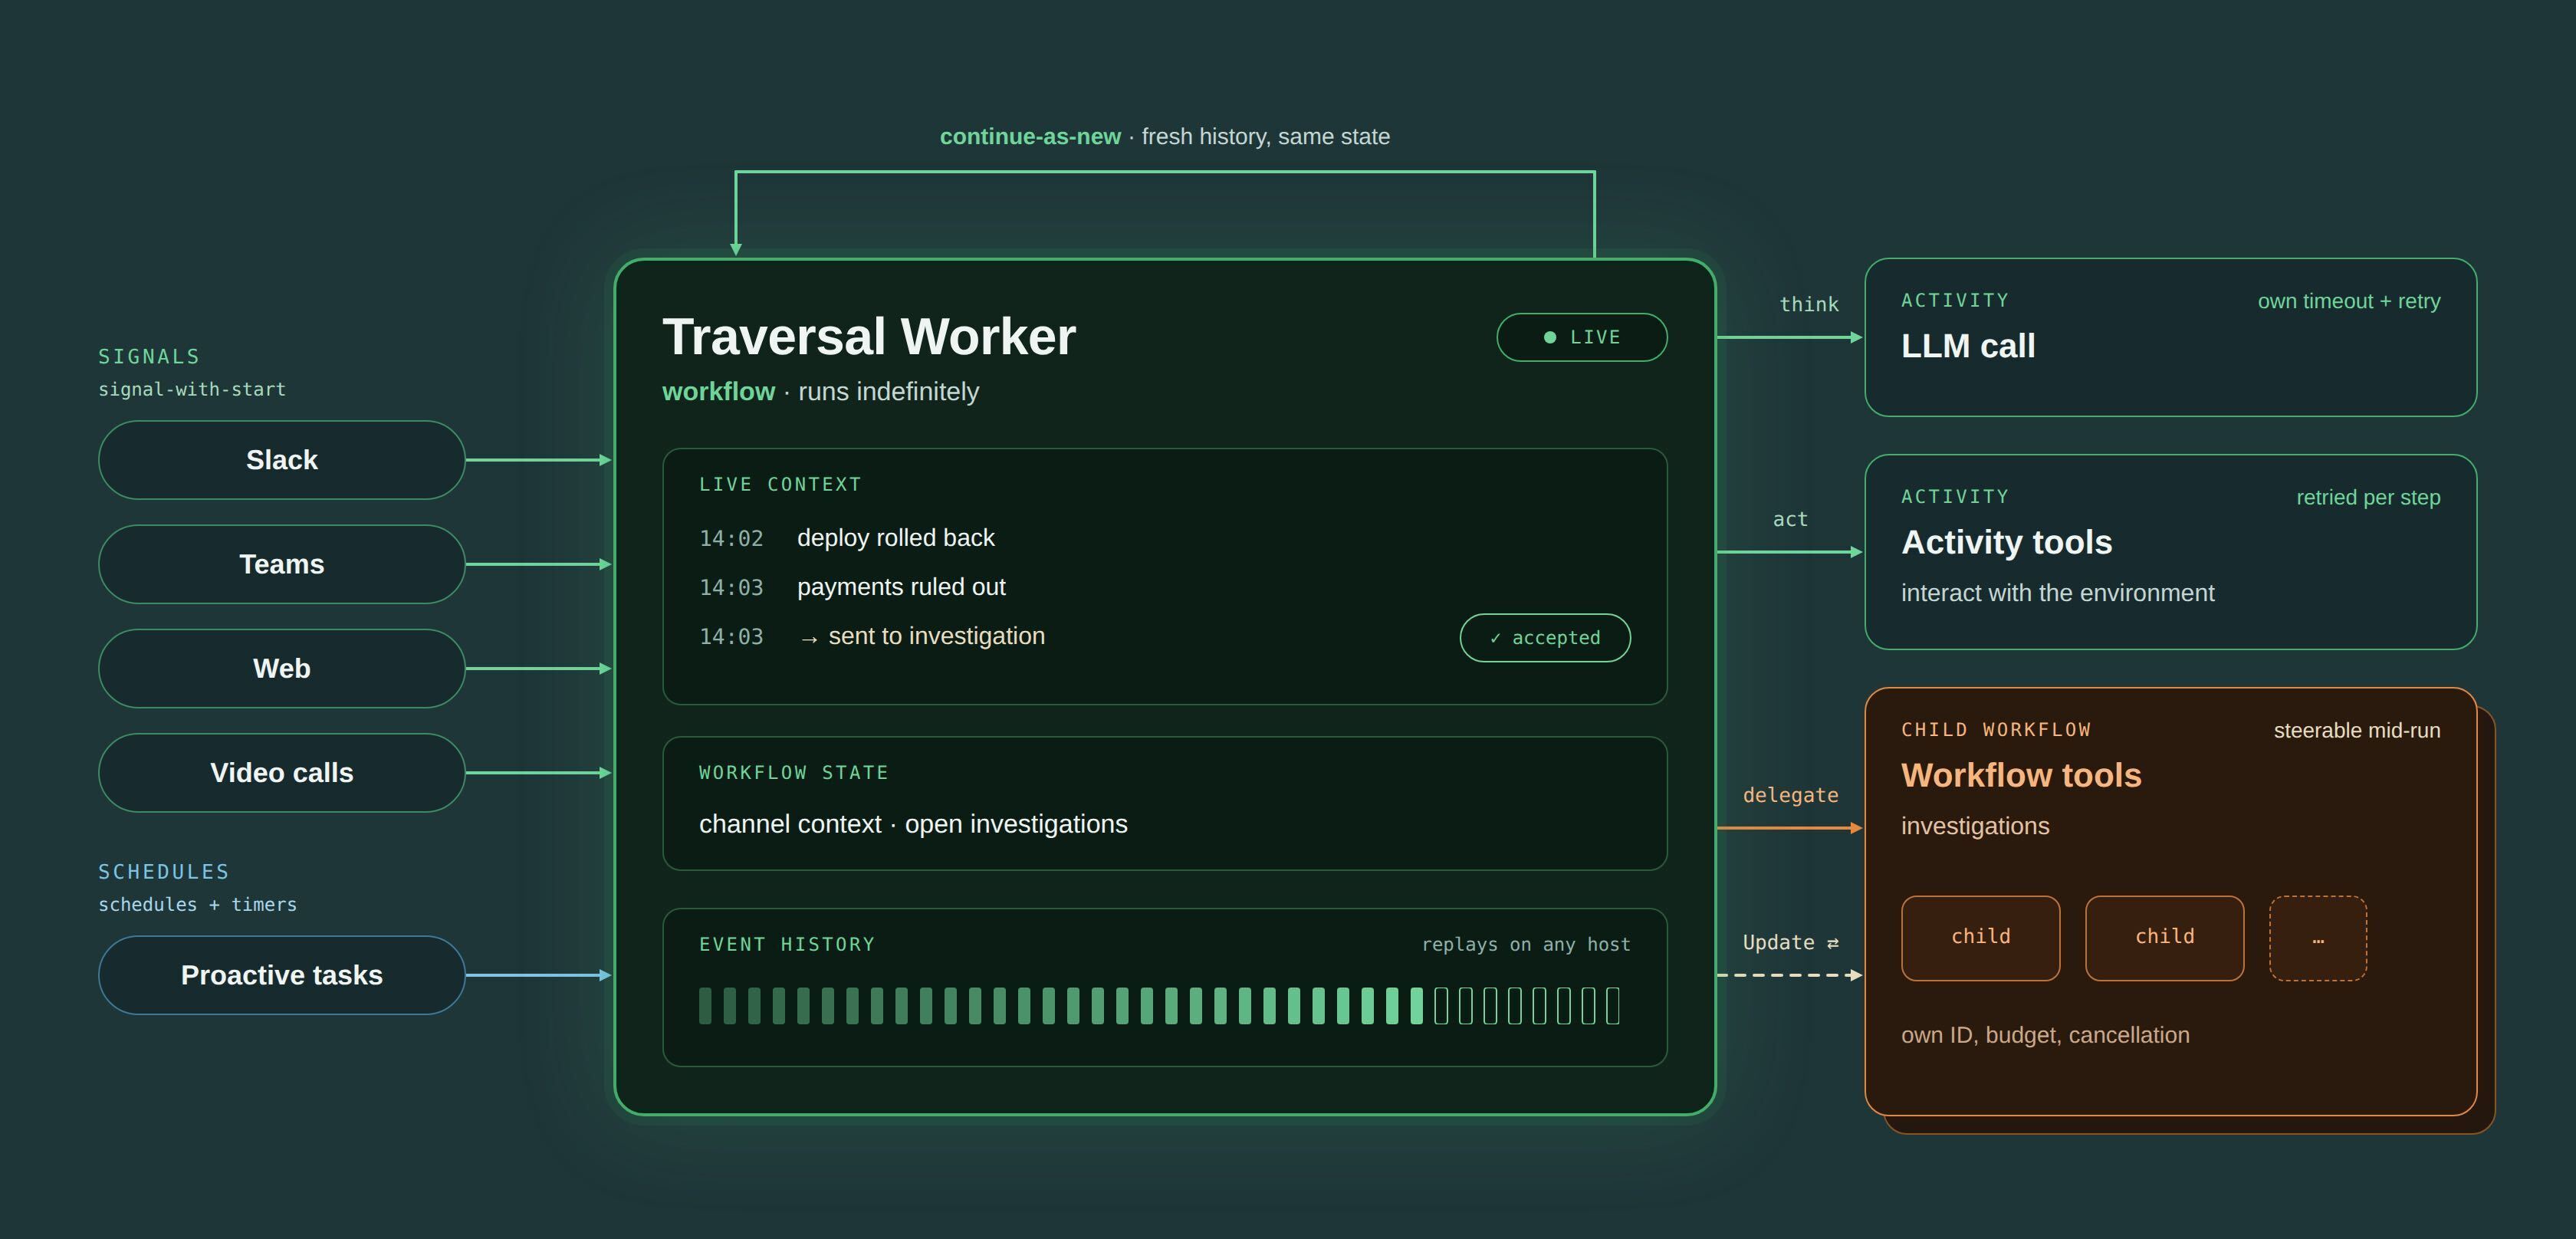
- The harness is a workflow. A workflow is a durable function. Its execution is recorded as an event history, so if the process running it ends, another Temporal worker replays that history and picks up where it left off. The core agent loop lives here but executes none of the work itself. It decides what happens next, whether that's one model call, three tool calls, a delegated question, or a conclusion, and dispatches each decision outward.
- Each step is an activity. Every model call is an activity, and so is every tool call. This is what makes retry granular: an analysis step that times out retries as that step, and everything already finished stays finished. It also lets each kind of work carry its own deadline. A model call and a query sharing a week of history shouldn't share a timeout.
- Delegated work is a child workflow. A child workflow is started by another workflow but has its own ID, budget, and cancellation. Sub-agents and long-running background analysis become addressable in their own right instead of being buried inside a parent process, and the parent collects their results at its next decision point rather than blocking on them.
- State lives in a durable ledger. This was most of the migration and the least visible part of it. Nothing can be handed directly from one activity to the next, because the process that ran the last one may already be gone. There are also limits on how much data can pass through a workflow's history, and an investigation's message history exceeds them early and keeps growing.
Each activity loads what it needs, does one thing, and saves its progress. The model messages, the evidence, the analysis results, and the sandbox assignment all had to become something an activity could reconstruct, rather than something the loop held in memory. Retry safety came out of the same work. A step that dies partway through has already written rows, so a retry clears them before rebuilding, and the agent never wakes up with half a turn duplicated in its own transcript.
The result is that finished work is never lost. Every completed step is durably recorded, so a failure anywhere in a run resumes from the last one instead of starting over. Capacity is no longer one investigation per slot, and analysis dispatched in the same turn genuinely runs in parallel. Latency becomes something you can locate, too. When someone asks what the agent is working on, the answer is on a timeline rather than buried in a log search.
The same thinking shaped our Traversal Worker harness, which is also custom-built and Temporal-native but leans on a different part of the platform. A Traversal Worker is a long-running agent that sits in an incident channel. Channel activity reaches it as signals, and a Worker’s workflow can lie dormant while idle, and wake from signals or for proactive tasks. Temporal schedules and timers cover work that needs to happen later. Different primitives, same principle: the hardest parts of a persistent agent get much simpler when the platform already owns them.
Stopping and steering
An investigation works through an enormous amount of evidence toward a single question, and constant interruptions would make it worse at its job.
Incidents don't accommodate that. A deploy gets rolled back, someone rules out a service, and the picture changes. An agent that can't be redirected mid-run keeps working from stale premises with undiminished confidence. Being able to reach into a running investigation and change its course is a requirement.
There are many ways to build that, but Temporal already provides a clean mechanism for passing new data into a running workflow. Commands arrive as Updates: typed requests into a running workflow that return a result synchronously. The caller learns immediately whether the command was accepted, or whether the run was already stopping or writing its conclusion. Nothing is fire-and-forget, and nothing has to poll to find out whether it landed.
Three kinds of callers use it:
- A Traversal Worker steers an investigation. A Worker in an incident channel is already following the conversation while an investigation runs. When the humans learn something new, the Worker forwards it into the run in flight, rather than starting a second run that has to rediscover everything.
- A person steers directly. The same two commands, new context or stop, are available from the UI or from Slack, against the session they're watching.
- An agent steers its sub-agents. Because delegated work is addressable, a parent can narrow a sub-agent's question when its own picture changes. A parent that stops takes its children with it, rather than leaving orphaned work writing into a shared sandbox.
Steering and stopping have different needs. New context is additive, so it waits for the next step boundary, where the agent's state is already written down and nothing is in flight. It arrives cleanly, the agent reads it like any other piece of evidence, and the wait is a matter of seconds.
A stop is different. When a stop arrives, the run may have model calls in flight, sub-agents working on delegated questions, a live, scoped shell open against the customer's cluster, a partially written transcript, and someone watching results stream in. All of it has to come to rest in a state that still makes sense.
So a stop cancels in-flight work and propagates to sub-agents, releases the sandbox, and closes out the transcript so the session can be picked up later. It tells everyone watching that the run ended and why, then finalizes with the findings the agent had already established. A stopped investigation hands back what it learned instead of throwing the work away.
None of this can be bolted on from outside. Stopping correctly means reaching into the same runtime the agent executes in, which is why these controls have to be native to the harness. Temporal primitives are what make that practical. Cancellation reaching the sub-agents is just child-workflow cancellation, and bringing the sandbox, transcript, and stream to rest is the finalize path running as ordinary workflow code once the stop lands.
What's next
Moving investigations onto Temporal workers got them off the API's critical path. Rebuilding the harness around Temporal primitives delivered the rest: granular retries, resumable runs, elastic capacity, and the step boundaries that make stopping and steering possible.
Our research team is pushing hard on what an RCA agent can do, and the harness has to keep pace. Owning it means we can move as fast as our research does, and building it on Temporal means the infrastructure keeps up. Read more of Traversal's research on our blog.